
FS-MoE
Sparse mixture-of-experts inference IP
Built for dynamically activated sparse models, carrying large parameter counts within an edge bandwidth budget.
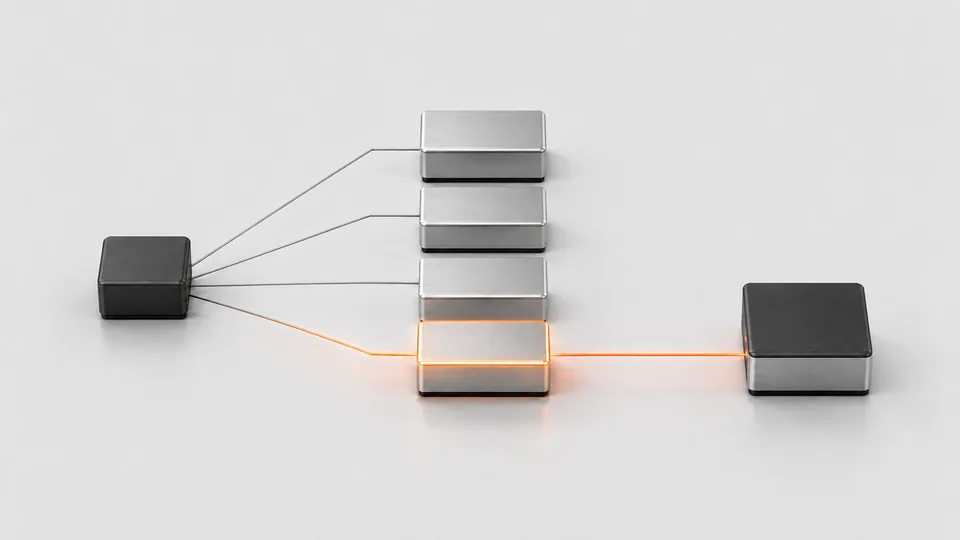
Data flow
Built for dynamically activated sparse models, carrying large parameter counts within an edge bandwidth budget.
Native support
Large sparse models on edge budgets
Deployment
ASIC tape-out and FPGA prototyping, with interface and system adaptation per project.
Licence includes
Inference core IP, FPGA evaluation board, model mapping and interface adaptation, design-in support.
IP coverage, interfaces, resource usage, performance targets and licensing terms are evaluated per target device and model.
Further reading
 FPGA Prototyping for LLM Accelerators: IP Licence to Tape-outRunning an LLM inference core on an FPGA before tape-out validates model mapping, interfaces and the system path. What an IP licence covers, step by step.
 What Is a Compute-in-Memory AI Chip? Three Routes ExplainedA compute-in-memory AI chip runs multiply-accumulate inside the memory array, so weights stop moving. How MaskROM, SRAM CIM and near-memory compute differ.
 How to Choose an Edge LLM Inference Chip: 7 QuestionsChoosing an edge LLM inference chip comes down to model fit, power budget and how the model updates, not peak TOPS. Seven questions to answer, plus a checklist.
Ask about FS-MoE
Tell us the target device, model and interfaces. We reply with IP coverage and an evaluation plan.